Two Unified Perspectives on DDPM
Two perspectives on DDPM through stochastic analysis and discrete-time Markov chains.
The LaTeX version of this blog post is available here. Or you can simply download the .tex and .pdf files from here. The content is the same, but the LaTeX version has a more formal typesetting, which I personally prefer (quite much).
In this article, we introduce two different perspectives on Denoising Diffusion Probabilistic Models (DDPM): one from stochastic analysis (continuous-time Markov chains, CTMC), and one from discrete-time Markov chains (used by the original DDPM paper Ho et al. (2020)). The material for the former is drawn from Zhang (2025, Advanced Algorithms).
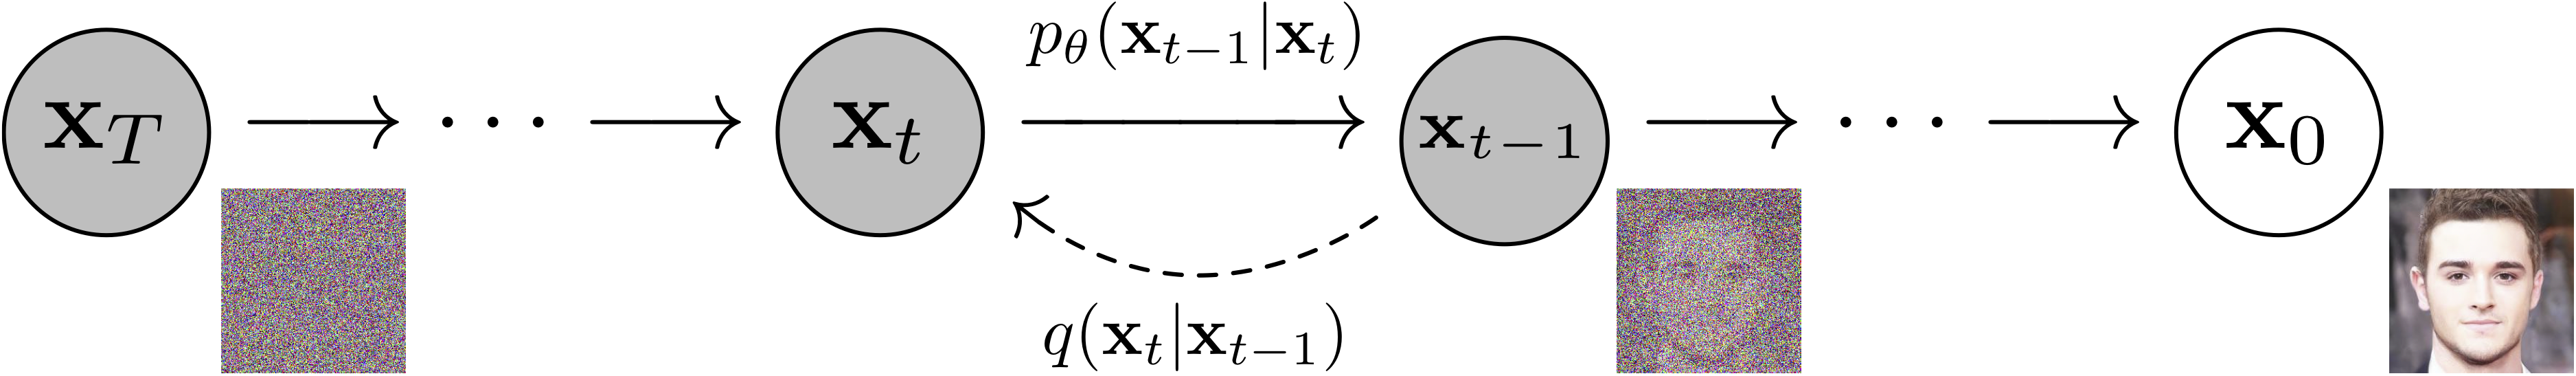 Forward diffusion and reverse denoising processes in DDPM (from Ho et al. (2020)).
DDPM consists of two stages. The forward process systematically destroys a complex data sample by gradually adding Gaussian noise to it. The reverse process learns to denoise a noisy sample step by step to recover a sample from the data distribution (e.g., the uniform distribution on a large image dataset).
The Stochastic Analysis Perspective
The forward process
Consider an Ornstein–Uhlenbeck (OU) process
\[\d X_t = -X_t\,\mathrm{d}t + \sqrt2\,\mathrm{d}W_t, \tag{1}\label{eq:ou}\]where $(W_t)_{t\ge0}$ is a standard Wiener process. Its solution is (by applying Itô’s formula to $f(t,X_t)=e^tX_t$)
\[X_t\overset{d}{=}e^{-t}X_0+\sqrt{1-e^{-2t}}\epsilon,\quad\epsilon\sim\mathcal{N}(0,I). \tag{2}\label{eq:ou_sol}\]As $t\to\infty$, $X_t$ converges in distribution to the standard Gaussian distribution. Hence, we can use $\eqref{eq:ou_sol}$ to simulate the OU process and systematically destroy a data sample $X_0$.
The reverse process
To learn the denoising process, consider the time-reversed process of $\eqref{eq:ou}$
\[Y_t=X_{T-t},\quad 0\le t\le T,\]where $T$ is chosen sufficiently large such that the law of $X_T$ is close to the standard Gaussian distribution. A tedious calculation (see Zhang (2025, Stochastic Processes)) yields the SDE for the reverse process:
\[\d Y_t = (Y_t + 2\nabla\log\pi_{T-t}(Y_t))\,\mathrm{d}t + \sqrt2\,\d\bar W_t, \tag{3}\label{eq:reverse_ou}\]where $\pi_t$ is the density of $X_t$.
To simulate $\eqref{eq:reverse_ou}$ (e.g., using Euler–Maruyama discretization), it suffices to know the value of $\nabla\log\pi_t(x)$ (known as the score function) for every $t$ and $x$. However, this function is generally intractable to compute directly. So we approximate it using a neural network. The following formula makes it convenient to learn the score function.
Let $Y = X + \sqrt t\cdot\epsilon$, where $\epsilon\sim\mathcal{N}(0,I)$ is independent of $X$. Let $p_Y$ be the density of $Y$. Then
\[\E[X \mid Y=y] = y + t\nabla\log p_Y(y).\]Recall from $\eqref{eq:ou_sol}$ that
\[\underbrace{X_t}_Y = \underbrace{e^{-t}X_0}_X + \underbrace{\sqrt{1-e^{-2t}}}_{\sqrt t}\epsilon,\quad\epsilon\sim\mathcal{N}(0,I).\]Since we can draw samples from the data distribution, we can construct $(x_0,x_t)$ pairs from the forward process, and train the network to predict $x_0$ from $x_t$ (and $t$). Use the ordinary MSE loss $\norm{x_0-\hat x_0}^2$. The solution to this easy optimization problem is
\[\hat x_0^*(x_t,t) = \E[x_0 \mid x_t].\]Substituting it into Tweedie’s formula yields the score function.
The Discrete-Time Markov Chain Perspective
The original implementation of DDPM differs from the approach described above in several ways. In particular, it uses discrete-time Markov chains instead of Itô diffusions to model the forward and reverse processes.
Noise schedule
Instead of using a CTMC (OU process), the original DDPM selects a set of timesteps $(\tau_t)_{0\le t\le T}$ and only considers the discrete-time Markov chain $x_t = X_{\tau_t}$, $0\le t\le T$. Specifically, DDPM defines
\[0<\alpha_t<1,\quad \beta_t = 1-\alpha_t,\quad \bar\alpha_t=\prod_{s=1}^{t}\alpha_s,\quad 1\le t\le T,\] \[x_t = \sqrt{\alpha_t}x_{t-1} + \sqrt{\beta_t}\epsilon,\quad\epsilon\sim\mathcal{N}(0,I). \tag{4}\label{eq:forward_one_step}\]Or, equivalently,
\[x_t = \sqrt{\bar\alpha_t}x_0 + \sqrt{1-\bar\alpha_t}\epsilon,\quad\epsilon\sim\mathcal{N}(0,I). \tag{5}\label{eq:forward}\]Set $\tau_t = -\frac12\log\bar\alpha_t$ and we can see that $\eqref{eq:forward}$ is completely equivalent to $\eqref{eq:ou_sol}$. Hence, the noise schedule is just about selecting a discrete set of timesteps.
The original DDPM paper sets $T=1000$ and linearly increases $\beta_t$ from $10^{-4}$ to $0.02$. The smallness of $\beta_t$ will be used in the asymptotic expansion below.
Prediction target
DDPM usually directly predicts the noise in $\eqref{eq:forward}$ using a neural network $\epsilon_\theta(x_t,t)$. The ordinary MSE loss is used:
\[L_{\mathrm{simple}}=\E_{x_0,t,\epsilon}[\norm{\epsilon-\epsilon_\theta(x_t,t)}^2],\quad t\sim\mathrm{Uniform}\{1,\dots,T\}.\]We show that this new prediction target is essentially just a reparameterization of score matching. Let $s_\theta(x_t,t)$ be the score estimator. The optimal noise predictor is $\epsilon^*(x_t,t)=\E[\epsilon\mid x_t]$. Take the conditional expectation of both sides of $\eqref{eq:forward}$ given $x_t$, and combine it with Tweedie’s formula.
\[s_\theta(x_t,t) = -\frac{\epsilon_\theta(x_t,t)}{\sqrt{1-\bar\alpha_t}},\qquad\hat x_0\mathrel{:=}\E[x_0\mid x_t]=\frac{x_t-\sqrt{1-\bar\alpha_t}\epsilon_\theta(x_t,t)}{\sqrt{\bar\alpha_t}}. \tag{6}\label{eq:score_x0_pred}\]Gaussian posterior
We will need the Gaussian posterior $q(x_{t-1}\mid x_t,x_0)$ in what follows.
\[\begin{aligned} q(x_{t-1}\mid x_t,x_0) &= \frac{q(x_{t-1}\mid x_0)q(x_t\mid x_{t-1},x_0)}{q(x_t\mid x_0)} \\ \text{(Markov property)}\quad &= \frac{q(x_{t-1}\mid x_0)q(x_t\mid x_{t-1})}{q(x_t\mid x_0)} \\ &= \phi\bra{\frac{x_{t-1}-\sqrt{\bar\alpha_{t-1}}x_0}{\sqrt{1-\bar\alpha_{t-1}}}} \phi\bra{\frac{x_t-\sqrt{\alpha_t}x_{t-1}}{\sqrt{1-\alpha_t}}} \phi\bra{\frac{x_t-\sqrt{\bar\alpha_t}x_0}{\sqrt{1-\bar\alpha_t}}}^{-1} \\ \text{(by a tedious calculation)}\quad &= \mathcal{N}(\tilde\mu_t,\tilde\beta_tI), \end{aligned}\]where $\phi$ is the standard Gaussian density, and
\[\tilde\mu_t=\frac{\sqrt{\bar\alpha_{t-1}}\beta_t}{1-\bar\alpha_t}x_0+\frac{\sqrt{\alpha_t}(1-\bar\alpha_{t-1})}{1-\bar\alpha_t}x_t,\qquad\tilde\beta_t=\frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t. \tag{7}\label{eq:posterior}\]Sampling
Definition
DDPM defines1
\[p_\theta(x_{t-1}\mid x_t) = \mathcal{N}(\mu_\theta(x_t,t),\sigma_t^2I),\]where $\sigma_t^2$ usually equals $\beta_t$ or $\tilde\beta_t$, and
\[\mu_\theta(x_t,t)=\frac1{\sqrt{\alpha_t}}\bra{x_t-\frac{\beta_t}{\sqrt{1-\bar\alpha_t}}\epsilon_\theta(x_t,t)}. \tag{8}\label{eq:post_mean}\]Here $\mu_\theta(x_t,t)$ is obtained by substituting $\hat x_0$ for $x_0$ in $\eqref{eq:posterior}$ (note that we no longer condition on $x_0$). During sampling, we start with $x_T\sim\mathcal{N}(0,I)$ and sample
\[x_{t-1} = \mu_\theta(x_t,t) + \sigma_tz,\quad t=T,\dots,1, \tag{9}\label{eq:sample}\]where we resample $z\sim\mathcal{N}(0,I)$ at each step, and set $z=0$ at the final step $t=1$.
Note that although we substitute $\hat x_0$ for $x_0$ to obtain $\mu_\theta(x_t,t)$, which seems inaccurate, it still holds that $\mu^*(x_t,t)=\E[x_{t-1}\mid x_t]$:
\[\E[x_{t-1}\mid x_t] = \E[\E[x_{t-1}\mid x_t,x_0]\mid x_t] = \E[\tilde\mu_t\mid x_t] = \frac{\sqrt{\bar\alpha_{t-1}}\beta_t}{1-\bar\alpha_t}\hat x_0+\frac{\sqrt{\alpha_t}(1-\bar\alpha_{t-1})}{1-\bar\alpha_t}x_t=\mu^*(x_t,t).\]Connection to the reverse SDE
We now show that the two perspectives are almost equivalent. Suppose $\sigma_t^2=\beta_t$. Combining $\eqref{eq:sample}$, $\eqref{eq:post_mean}$, and $\eqref{eq:score_x0_pred}$ yields
\[\begin{aligned} x_{t-1} &= \frac{x_t+\beta_t s_\theta(x_t,t)}{\sqrt{1-\beta_t}} + \sqrt{\beta_t}z \\ \text{(Taylor expand in $\beta_t$)}\quad &= x_t + \frac{\beta_t}{2}x_t + \beta_t s_\theta(x_t,t) + O(\beta_t^2) + \sqrt{\beta_t}z \\ \text{($h\mathrel{:=}\beta_t/2$)}\quad &\approx x_t + (x_t + 2s_\theta(x_t,t))h + \sqrt{2h}z. \end{aligned}\]This coincides with the Euler–Maruyama discretization of $\eqref{eq:reverse_ou}$. Moreover, the step size $h$ also matches that in the discretized forward process $\eqref{eq:forward_one_step}$:
\[h_{\mathrm{forward}} = \tau_t - \tau_{t-1} = -\frac12\log(1-\beta_t)\approx\frac{\beta_t}{2}.\]Loss function
Reparameterization changes the loss weights across timesteps
The reverse process uses equally weighted original-image MSE, while now we use equally weighted noise MSE. $\eqref{eq:score_x0_pred}$ shows the difference between the two:
\[\norm{\epsilon-\epsilon_\theta}^2 = \frac{\bar\alpha_t}{1-\bar\alpha_t}\norm{x_0-\hat x_0}^2.\]Therefore, noise MSE is the signal-to-noise ratio-weighted original-image MSE. The reparameterization changes the loss weights across timesteps and shifts the focus of training.
An ELBO-based loss function
We can use the evidence lower bound (ELBO) to derive an alternative loss function. To do this, define the model’s joint distribution $p_\theta(x_{0:T})$ and the forward distribution $q(x_{1:T}\mid x_0)$. They factorize as
\[p_\theta(x_{0:T}) = \phi(x_T)\prod_{t=1}^{T}p_\theta(x_{t-1}\mid x_t),\qquad q(x_{1:T}\mid x_0) = q(x_T\mid x_0)\prod_{t=2}^{T}q(x_{t-1}\mid x_t,x_0). \tag{10}\label{eq:factorize}\]Here we use the Markov property. Now ELBO gives
\[\begin{aligned} \log p_\theta(x_0) &\ge \E_{q(x_{1:T}\mid x_0)}\sbra{\log\frac{p_\theta(x_{0:T})}{q(x_{1:T}\mid x_0)}} \\ &= \E_{q(x_{1:T}\mid x_0)}\sbra{\log\frac{\phi(x_T)}{q(x_T\mid x_0)}+\sum_{t=2}^{T}\log\frac{p_\theta(x_{t-1}\mid x_t)}{q(x_{t-1}\mid x_t,x_0)}+\log p_\theta(x_0\mid x_1)} \\ &= -L_{\mathrm{VLB}}, \end{aligned}\]where VLB stands for variational lower bound and
\[L_{\mathrm{VLB}} = \E\sbra{\underbrace{\KL{q(x_T\mid x_0)}{\phi(x_T)}}_{L_T} + \sum_{t=2}^{T}\underbrace{\KL{q(x_{t-1}\mid x_t,x_0)}{p_\theta(x_{t-1}\mid x_t)}}_{L_{t-1}} - \underbrace{\log p_\theta(x_0\mid x_1)}_{\text{reconstruction loss}}}.\]Let’s look at $L_T$ first. Because
\[q(x_T\mid x_0)=\mathcal{N}(\sqrt{\bar\alpha_T}x_0,(1-\bar\alpha_T)I),\qquad p(x_T)=\mathcal{N}(0,I),\]$L_T$ does not depend on $\theta$ and thus can be ignored during training.
Now consider $L_{t-1}$. We already know that
\[q(x_{t-1}\mid x_t,x_0)=\mathcal{N}(\tilde\mu_t,\tilde\beta_tI),\qquad p_\theta(x_{t-1}\mid x_t)=\mathcal{N}(\mu_\theta,\sigma_t^2I).\]Hence
\[D_{\mathrm{KL}}=\frac{\norm{\tilde\mu_t-\mu_\theta}^2}{2\sigma_t^2}+\underbrace{\frac d2\bra{\frac{\tilde\beta_t}{\sigma_t^2}-1+\log\frac{\sigma_t^2}{\tilde\beta_t}}}_{\text{not depending on $\theta$}}.\] \[L_{t-1}=\E_{x_0,\epsilon}\sbra{\frac{\beta_t^2}{2\sigma_t^2\alpha_t(1-\bar\alpha_t)}\norm{\epsilon-\epsilon_\theta(x_t,t)}^2}+C_t.\]Here $d$ is the data dimension and $C_t$ is a constant that does not depend on $\theta$.
Now consider the reconstruction loss. Direct calculation yields
\[L_0=\E_{x_0,\epsilon}\sbra{\frac{\beta_1}{2\sigma_1^2\alpha_1}\norm{\epsilon-\epsilon_\theta(x_t,t)}^2}+C.\]Note that in the original DDPM implementation, $L_{\mathrm{simple}}$ is adopted instead of this fancier ELBO-based loss $L_{\mathrm{VLB}}$, because the former just works better.
References
- Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising Diffusion Probabilistic Models. Advances in Neural Information Processing Systems, 33:6840–6851, 2020.
- Chihao Zhang. Advanced Algorithms, Lecture 7: Markov Semigroup, Langevin Dynamics, and DDPMs. Lecture notes, 2025.
- Chihao Zhang. Stochastic Processes, Lecture 14: Markov Processes, Langevin Monte Carlo, and Diffusion Models. Lecture notes, 2025.
Footnotes
Note that although $q(x_{t-1}\mid x_t,x_0)$ is Gaussian, $q(x_{t-1}\mid x_t)$ in general is not. ↩︎